A design review about a "slow LLM" usually starts as a pile.
Latency. Cost. Quality. The model. We should add a cache. Users are complaining. Maybe a bigger GPU. The prompt is too long.
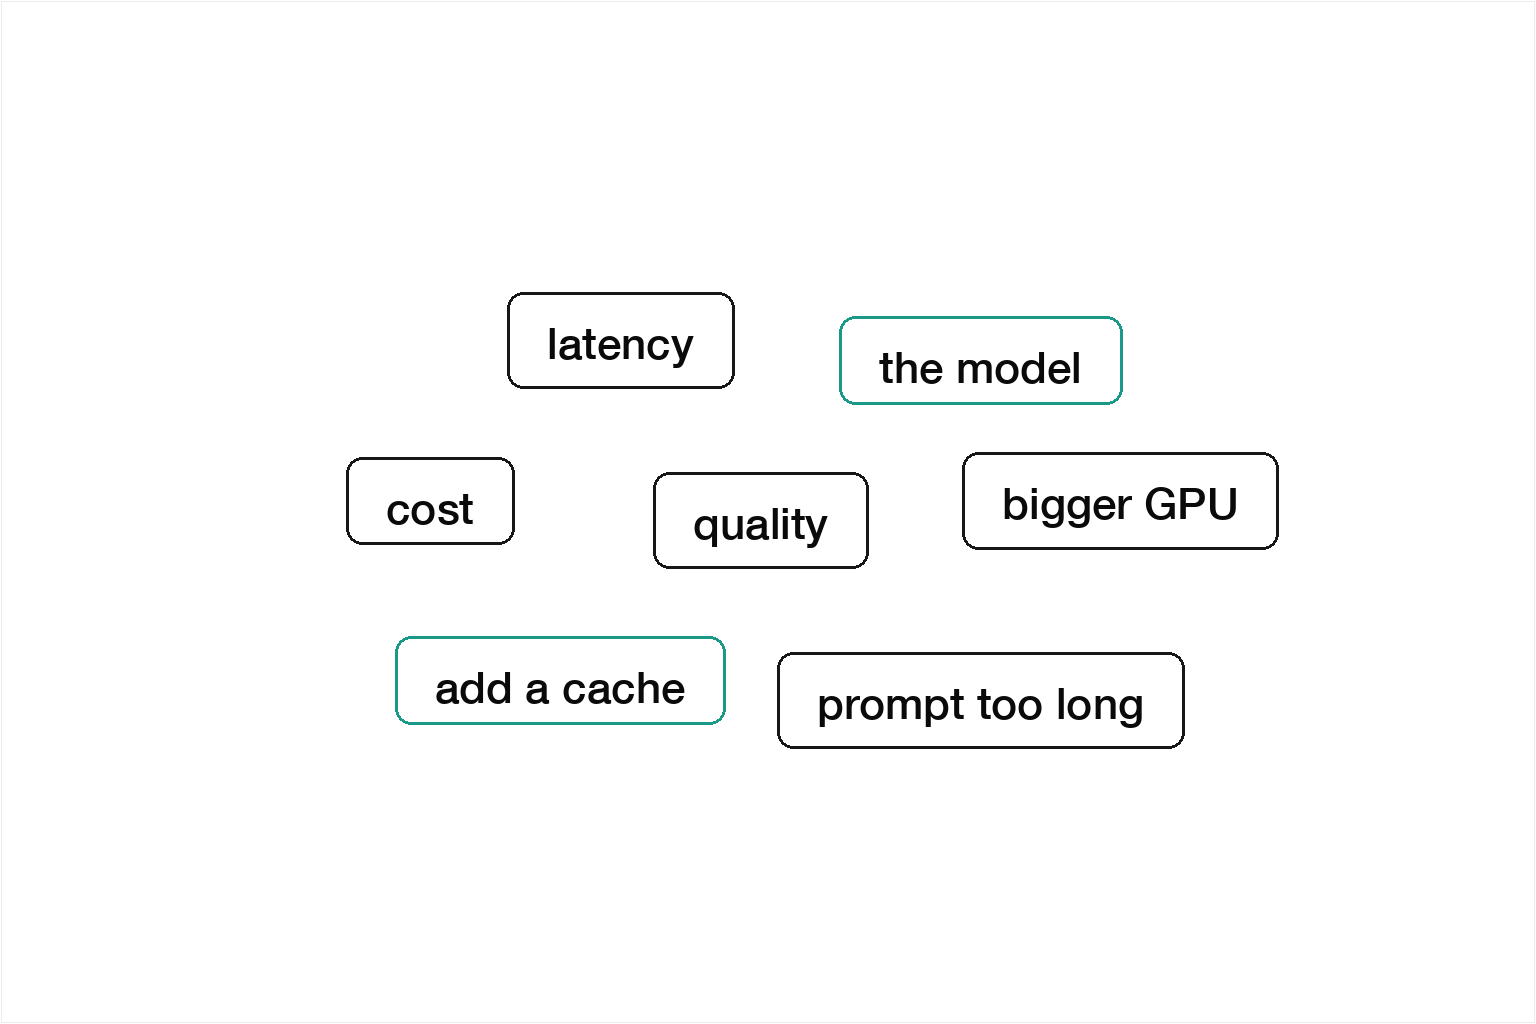
I've sat in that review more than once. Everyone has a word. None of them are quite the same kind of thing. Latency and "the prompt is too long" can be the same fact. Cost and a bigger GPU are a constraint and a bet. Quality keeps interrupting because it has nowhere else to go. You argue the same point twice, under different names, and then someone asks about the tool call and the meeting restarts.
If you've never heard MECE, that's the whole idea: a list that doesn't overlap, and doesn't leave a hole in the question you asked. Mutually exclusive, collectively exhaustive. The name is just those two phrases. I keep running into the same mess in postmortems, doc outlines, eval labels — anywhere a list is pretending to be a structure. The slow-LLM pile is just the one I see most. The rule isn't about LLMs.
The room said slow LLM
That's the pile's name, not the question. Keep slow LLM and the only honest buckets are prefill and decode. Retrieval and tools don't belong, and you miss the wait that isn't the model.
People said the LLM was slow. What they meant was the user is waiting.
So ask that: where is the user waiting on this request? Prefill, decode, retrieval, tools. Same kind of answer — a place time can go.
Don't swap it for "how do we make it faster." That's a wish. Every hobby in the company fits.
For the review I want three questions, not one: where is the wait, what can we change, and what will we accept?
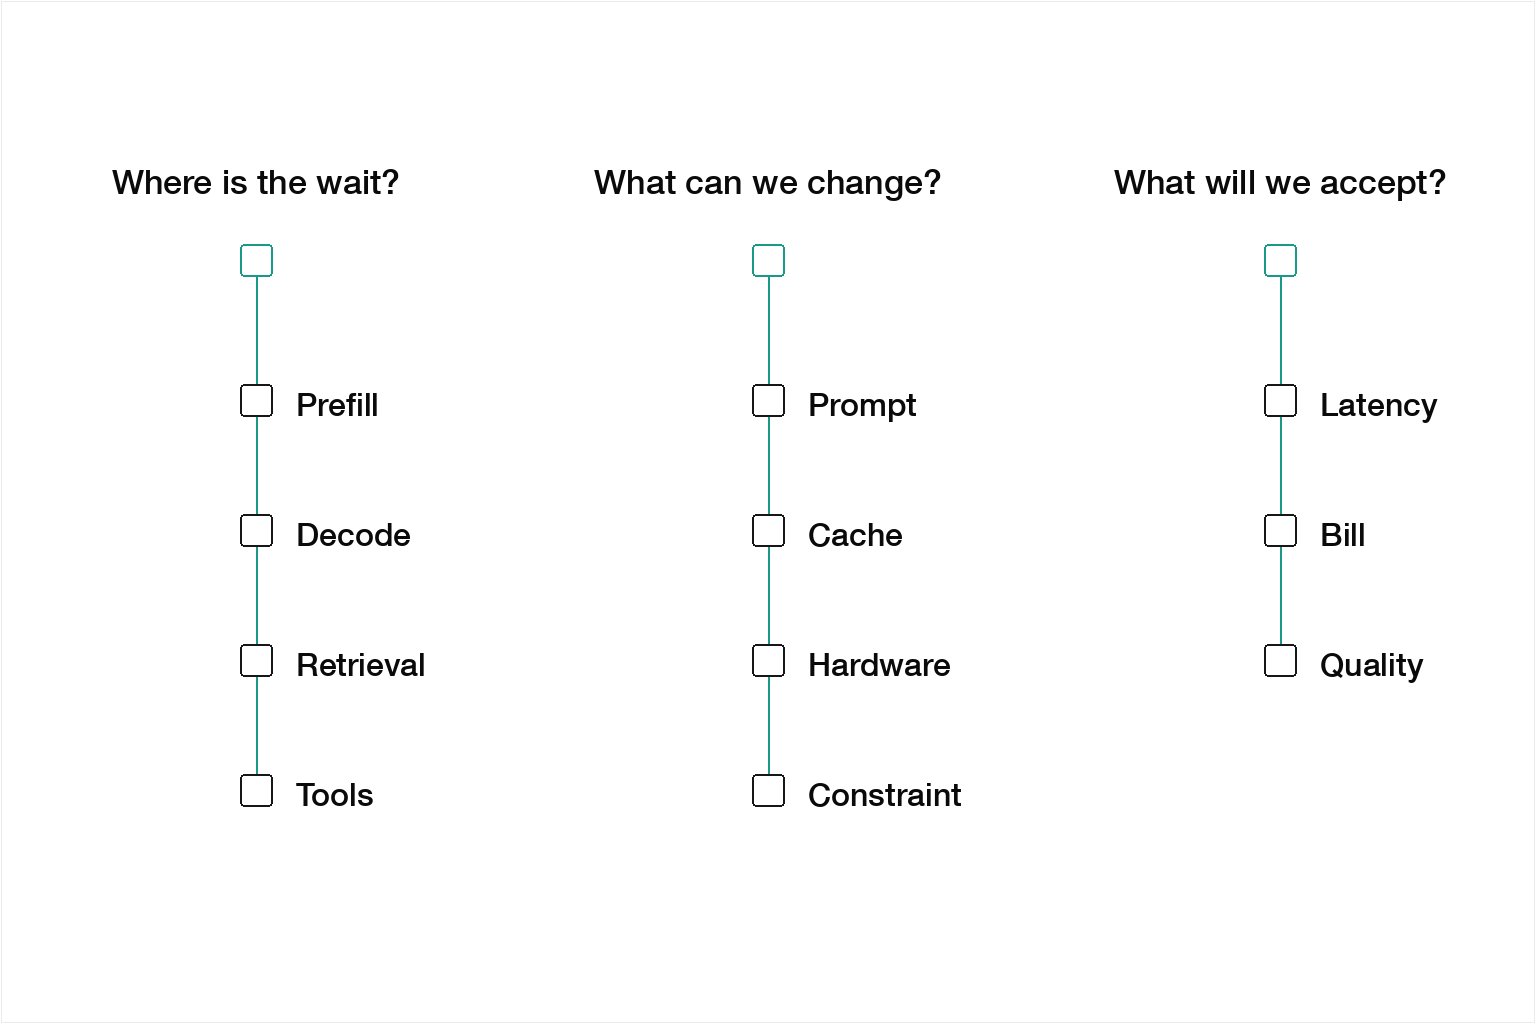
"Add a cache" is a change. It only matters if the wait is in prefill on a prefix you can reuse. "Users are complaining" is why you booked the room. Quality is a floor, not a speed fix. The model is usually none of these. Swap it last.
| What someone said | Where it actually goes |
|---|---|
| The prompt is too long | Prefill, then the prompt |
| We should add a cache | A change — only if the prefix is stable |
| Maybe a bigger GPU | Hardware — after you know decode is the bill |
| Quality | What we'll accept, not a speed fix |
| The model | Usually nowhere in this cut. Swap it last. |
You can disagree with a row. That's the point. Now you're arguing about a place, not trading slogans. The review, if you write it down, is those three questions in that order.
Same mess, different surface
I see this on eval dashboards too. A bad Chat-with-Data answer gets tagged "the model failed." It was a retrieval miss, or bad SQL, or the question had no single answer. Overlap and the chart lies. A missing label and you spend a week on the prompt.
Don't get precious about it
This is a draft of the space, not the truth. A prefix cache can move wait and cost at the same time. Say that. Don't invent a fake clean split so the diagram looks pretty.
Exhaustive also doesn't mean infinite. It means exhaustive for the question you asked. "Where is the user waiting on this request?" is done when you have prefill, decode, retrieval, and tools. It is not a theory of everything that can go wrong. If you need incidents, ask a different question.
I'd rather keep a messy list than four neat boxes and a bucket named Other. Other is the leftovers you couldn't place — a missing sibling, or a parent that's still too wide. The diagram looks finished. The cut isn't.
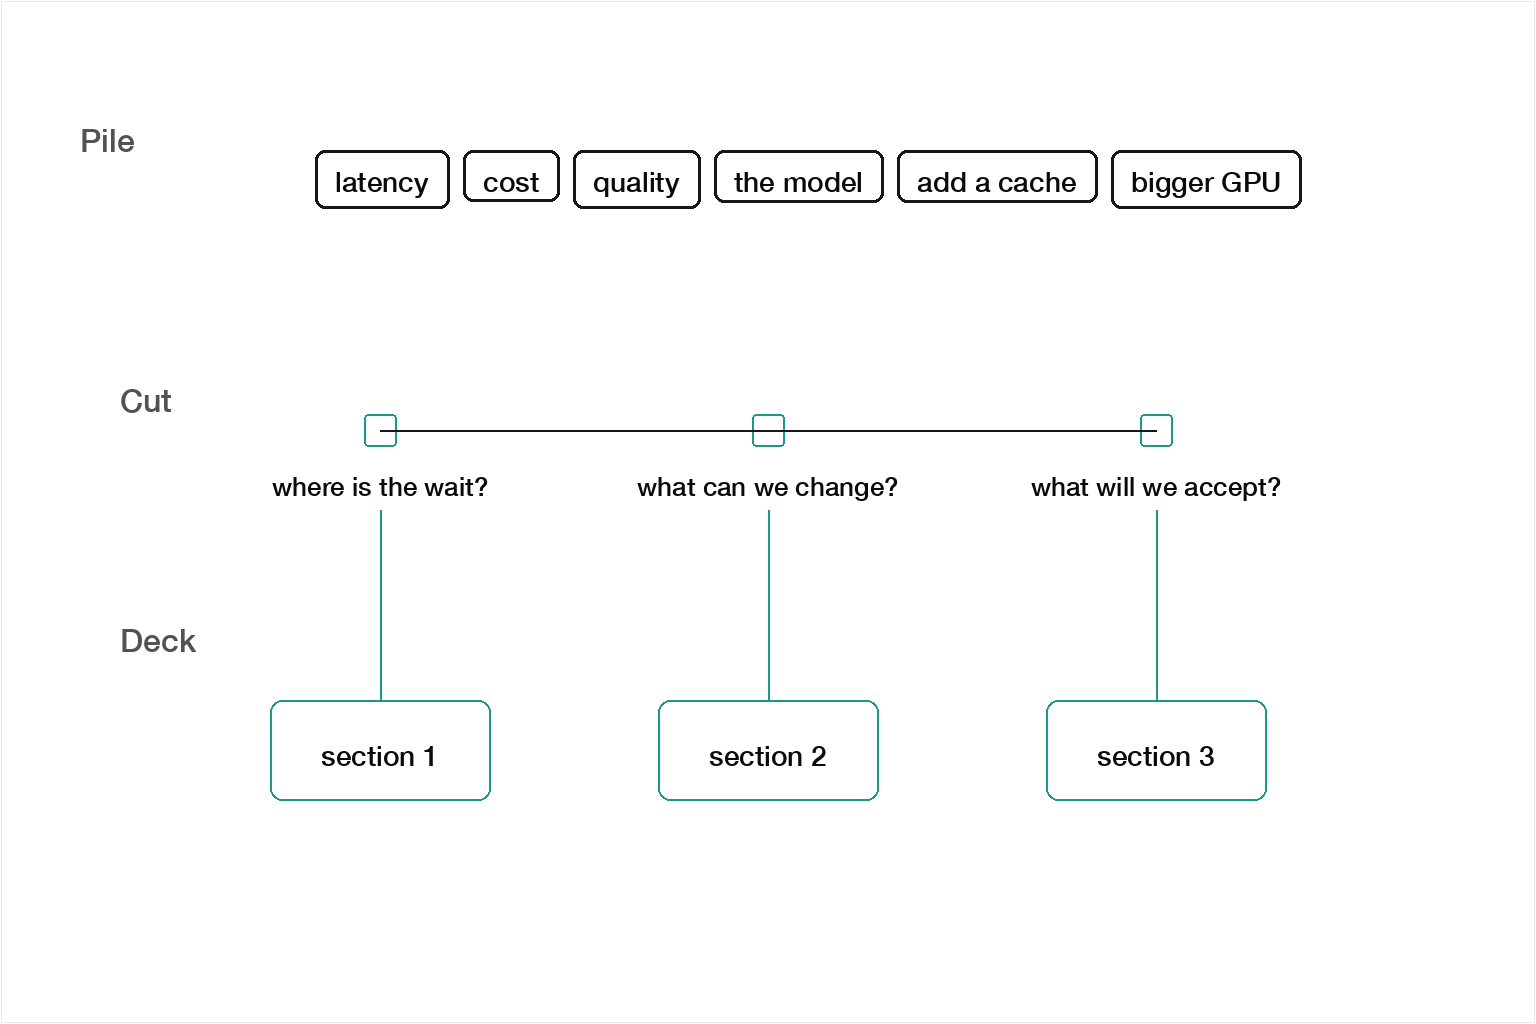
If something in the pile fits two places, or fits nowhere and you didn't mean to leave it out, you're not done. Go back to the question. A wider one will not help.